利用python爬取斗鱼app中照片方法实例
前言
没想到python是如此强大,令人着迷,以前看见图片总是一张一张复制粘贴,现在好了,学会python就可以用程序将一张张图片,保存下来。
最近看到斗鱼里的照片都不错,决定用最新学习的python技术进行爬取,下面将实现的过程分享出来供大家参考,下面话不多说了,来一起看看详细的介绍吧。
方法如下:
首先下载一个斗鱼(不下载也可以,url都在这了对吧)
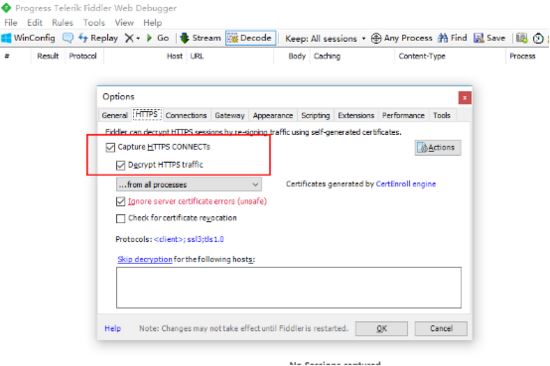
通过抓包,抓取到一个json的数据包,得到下面的地址

观察测试可知,通过修改offset值就是相当于app的翻页
访问这个url,返回得到的是一个大字典,字典里面两个索引,一个error,一个data。而data又是一个长度为20的数组,每个数组又是一个字典。每个字典中又有一个索引,vertical_src。
我们的目标就是它了!
import urllib.parse
import urllib
import json
import urllib.request
data_info={}
data_info['type']='AUTO'
data_info['doctype']='json'
data_info['xmlVersion']='1.6'
data_info['ue']='UTF-8'
data_info['typoResult']='true'
head_info={}
head_info['User-Agent']='DYZB/2.271 (iphone; iOS 9.3.2; Scale/3.00)'
url='http://capi.douyucdn.cn/api/v1/getVerticalRoom?aid=ios&client_sys=ios&limit=20&offset=20'
data_info=urllib.parse.urlencode(data_info).encode('utf-8')
print(data_info)
requ=urllib.request.Request(url,data_info)
requ.add_header('Referer','http://capi.douyucdn.cn')
requ.add_header('User-Agent','DYZB/2.271 (iphone; iOS 9.3.2; Scale/3.00)')
response=urllib.request.urlopen(requ)
print(response)
html=response.read().decode('utf-8')
这短短20多行代码就能返回得到json数据了。然后再通过对这json代码的切片,分离得到每个主播照片的url地址。
然后得到这一页的照片
import json
import urllib.request
data_info={}
data_info['type']='AUTO'
data_info['doctype']='json'
data_info['xmlVersion']='1.6'
data_info['ue']='UTF-8'
data_info['typoResult']='true'

url+str(i)='http://capi.douyucdn.cn/api/v1/getVerticalRoom?aid=ios&client_sys=ios&limit=20&offset='+str(x)
data_info=urllib.parse.urlencode(data_info).encode('utf-8')
print(data_info)
requ=urllib.request.Request(url,data_info)
requ.add_header('Referer','http://capi.douyucdn.cn')
requ.add_header('User-Agent','DYZB/2.271 (iphone; iOS 9.3.2; Scale/3.00)')
response=urllib.request.urlopen(requ)
print(response)
html=response.read().decode('utf-8')
'''
 print(type(dictionary))
print(type(dictionary[data]))
'''
dictionary=json.loads(html)
data_arr=dictionary["data"]
for i in range(0,19):
  name=data_arr[i]["nickname"]
  img_url=data_arr[i]["vertical_src"]
  print(type(img_url))
  respon_tem=urllib.request.urlopen(img_url)
  anchor_img=respon_tem.read()
  with open('../photos/'+name+'.jpg','wb') as f:
    f.write(anchor_img)
然后修改一下,让它有了翻页的功能
import urllib.parse
import urllib
import json
import urllib.request
data_info={}
data_info['type']='AUTO'
data_info['doctype']='json'
data_info['xmlVersion']='1.6'
data_info['ue']='UTF-8'
data_info['typoResult']='true'
data_info=urllib.parse.urlencode(data_info).encode('utf-8')

for x in range(0,195):
  url='http://capi.douyucdn.cn/api/v1/getVerticalRoom?aid=ios&client_sys=ios&limit=20&offset='+str(x)
  print(data_info)
  requ=urllib.request.Request(url,data_info)
  requ.add_header('Referer','http://capi.douyucdn.cn')
  requ.add_header('User-Agent','DYZB/2.271 (iphone; iOS 9.3.2; Scale/3.00)')
  response=urllib.request.urlopen(requ)
  print(response)
  html=response.read().decode('utf-8')
  dictionary=json.loads(html)
  data_arr=dictionary["data"]
  for i in range(0,19):
    name=data_arr[i]["nickname"]
    img_url=data_arr[i]["vertical_src"]
    print(type(img_url))
    respon_tem=urllib.request.urlopen(img_url)
    anchor_img=respon_tem.read()
    with open('../photos/'+name+'.jpg','wb') as f:
      f.write(anchor_img)
然后就等着吧~~
总结
以上就是这篇文章的全部内容了,希望本文的内容对大家的学习或者工作具有一定的参考学习价值,如果有疑问大家可以留言交流,谢谢大家对【听图阁-专注于Python设计】的支持。