python3.7简单的爬虫实例详解
python3.7简单的爬虫,具体代码如下所示:
#https://www.runoob.com/w3cnote/python-spider-intro.html

#Python 爬虫介绍

import urllib.parse
import urllib.request
from http import cookiejar
url = "http://www.baidu.com"
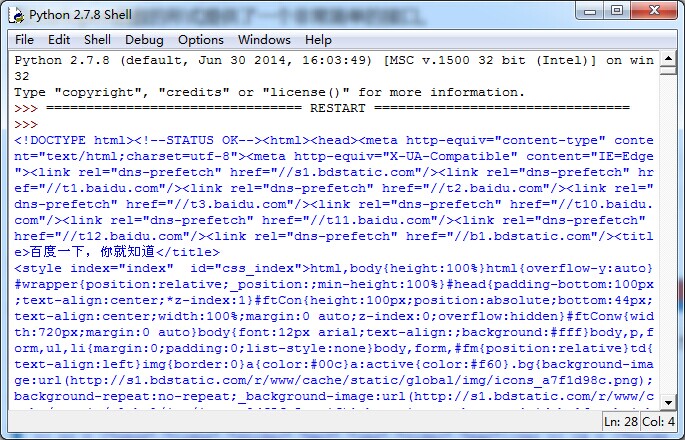
response1 = urllib.request.urlopen(url)
print("第一种方法")
#获取状态码,200表示成功
print(response1.getcode())
#获取网页内容的长度
print(str(response1.read()))
print(len(response1.read()))
print("第二种方法")
request = urllib.request.Request(url)
#模拟Mozilla浏览器进行爬虫
request.add_header("user-agent","Mozilla/5.0")
response2 = urllib.request.urlopen(request)
print(response2.getcode())
print(len(response2.read()))
print("第三种方法")
cookie = cookiejar.CookieJar()
#加入urllib2处理cookie的能力#
opener = urllib.request.build_opener(urllib.request.HTTPCookieProcessor(cookie))
urllib.request.install_opener(opener)
response3 = urllib.request.urlopen(url)
print(response3.getcode())
print(len(response3.read()))
print(cookie)
code: https://github.com/pascal19821003/python
path: python/study/tutorial/pachong/1.py
总结
以上所述是小编给大家介绍的python3.7简单的爬虫实例详解,希望对大家有所帮助,如果大家有任何疑问请给我留言,小编会及时回复大家的。在此也非常感谢大家对【听图阁-专注于Python设计】网站的支持!
如果你觉得本文对你有帮助,欢迎转载,烦请注明出处,谢谢!