解决Python中pandas读取*.csv文件出现编码问题
1、问题
在使用Python中pandas读取csv文件时,由于文件编码格式出现以下问题:
Traceback (most recent call last):
 File "pandas\_libs\parsers.pyx", line 1134, in pandas._libs.parsers.TextReader._convert_tokens
 File "pandas\_libs\parsers.pyx", line 1240, in pandas._libs.parsers.TextReader._convert_with_dtype
 File "pandas\_libs\parsers.pyx", line 1256, in pandas._libs.parsers.TextReader._string_convert
 File "pandas\_libs\parsers.pyx", line 1494, in pandas._libs.parsers._string_box_utf8
UnicodeDecodeError: 'utf-8' codec can't decode byte 0xa0 in position 19: invalid start byte
During handling of the above exception, another exception occurred:
Traceback (most recent call last):
 File "E:\PyCharm 2017.3.4\helpers\pydev\pydevd.py", line 1668, in <module>
  main()
 File "E:\PyCharm 2017.3.4\helpers\pydev\pydevd.py", line 1662, in main
  globals = debugger.run(setup['file'], None, None, is_module)
 File "E:\PyCharm 2017.3.4\helpers\pydev\pydevd.py", line 1072, in run
  pydev_imports.execfile(file, globals, locals) # execute the script
 File "E:\PyCharm 2017.3.4\helpers\pydev\_pydev_imps\_pydev_execfile.py", line 18, in execfile
  exec(compile(contents+"\n", file, 'exec'), glob, loc)
 File "F:/OneDrive - emails.bjut.edu.cn/Program/Python/DCAE/test.py", line 18, in <module>
  load_phenotypes_ABIDE2_RfMRIMaps()
 File "F:/OneDrive - emails.bjut.edu.cn/Program/Python/DCAE\Data\load_data.py", line 109, in load_phenotypes_ABIDE2_RfMRIMaps
  pheno = pd.read_csv(pheno_path)
 File "E:\Python\Python35\lib\site-packages\pandas\io\parsers.py", line 678, in parser_f
  return _read(filepath_or_buffer, kwds)
 File "E:\Python\Python35\lib\site-packages\pandas\io\parsers.py", line 446, in _read
  data = parser.read(nrows)
 File "E:\Python\Python35\lib\site-packages\pandas\io\parsers.py", line 1036, in read
  ret = self._engine.read(nrows)
 File "E:\Python\Python35\lib\site-packages\pandas\io\parsers.py", line 1848, in read
  data = self._reader.read(nrows)
 File "pandas\_libs\parsers.pyx", line 876, in pandas._libs.parsers.TextReader.read
 File "pandas\_libs\parsers.pyx", line 891, in pandas._libs.parsers.TextReader._read_low_memory
 File "pandas\_libs\parsers.pyx", line 968, in pandas._libs.parsers.TextReader._read_rows
 File "pandas\_libs\parsers.pyx", line 1094, in pandas._libs.parsers.TextReader._convert_column_data
 File "pandas\_libs\parsers.pyx", line 1141, in pandas._libs.parsers.TextReader._convert_tokens
 File "pandas\_libs\parsers.pyx", line 1240, in pandas._libs.parsers.TextReader._convert_with_dtype
 File "pandas\_libs\parsers.pyx", line 1256, in pandas._libs.parsers.TextReader._string_convert
 File "pandas\_libs\parsers.pyx", line 1494, in pandas._libs.parsers._string_box_utf8
UnicodeDecodeError: 'utf-8' codec can't decode byte 0xa0 in position 19: invalid start byte
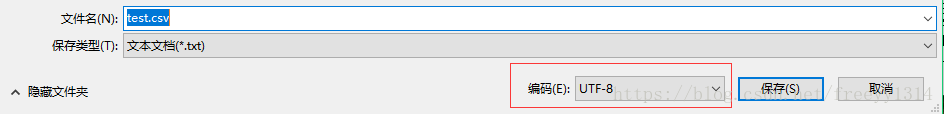
我认为该问题是由于文件编码格式不是'utf-8'所导致的,因此,尝试将文件格式进行转换,转换方式如下:
首先使用txt文本打开文件,然后另存为,在右下角将编码改为‘UTF-8',点击保存即可
总结
以上所述是小编给大家介绍的解决Python中pandas读取*.csv文件出现编码问题 ,希望对大家有所帮助,如果大家有任何疑问请给我留言,小编会及时回复大家的。在此也非常感谢大家对【听图阁-专注于Python设计】网站的支持!
如果你觉得本文对你有帮助,欢迎转载,烦请注明出处,谢谢!